
Custom scorecards and quality trends
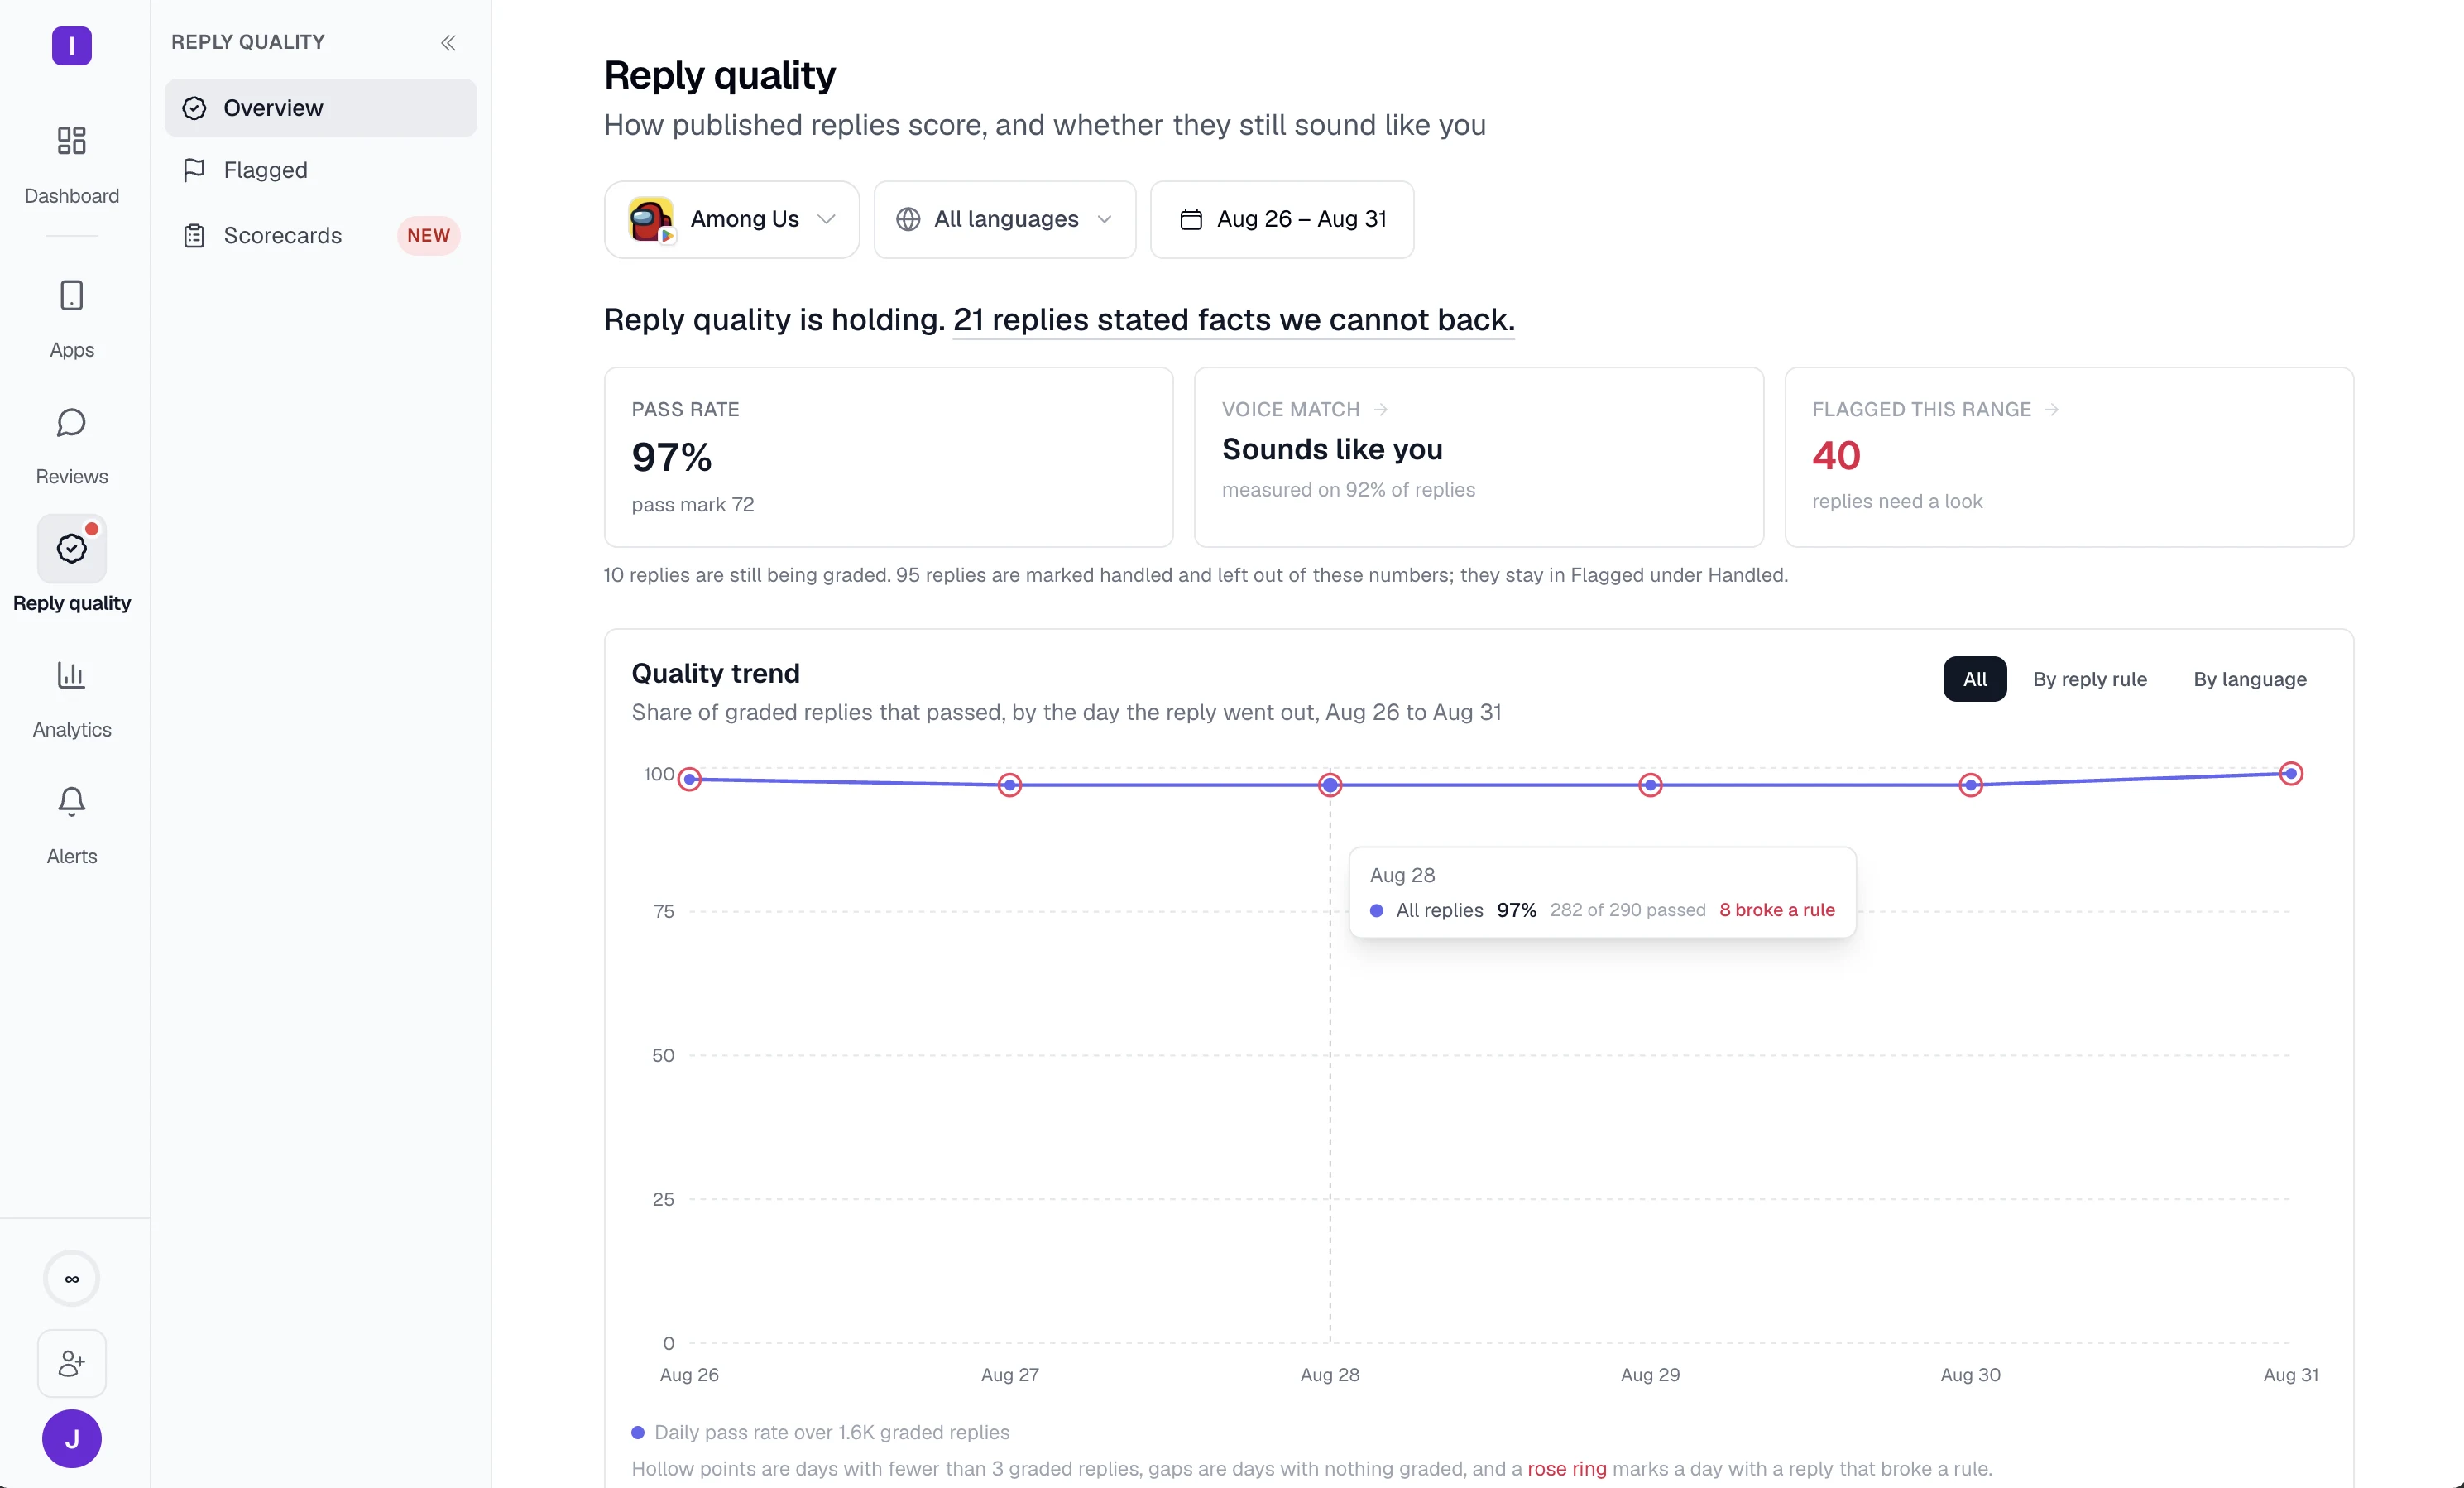
Choose your checks, add custom ones, and track the share of replies that pass. Compare rules and languages to find where quality drops. Each result keeps the checklist version used to score it.
AppReply is the platform that closes the loop on brand-critical replies. Set your quality checklist and turn on a monitor: matching replies are checked after they publish, flagging wrong answers, language mistakes, and changes in tone. Your team reviews the exceptions.
Included in Pro · Checks AI drafts before publishing and all or selected replies after
Trusted by teams behind apps with 1.7B+ combined downloads


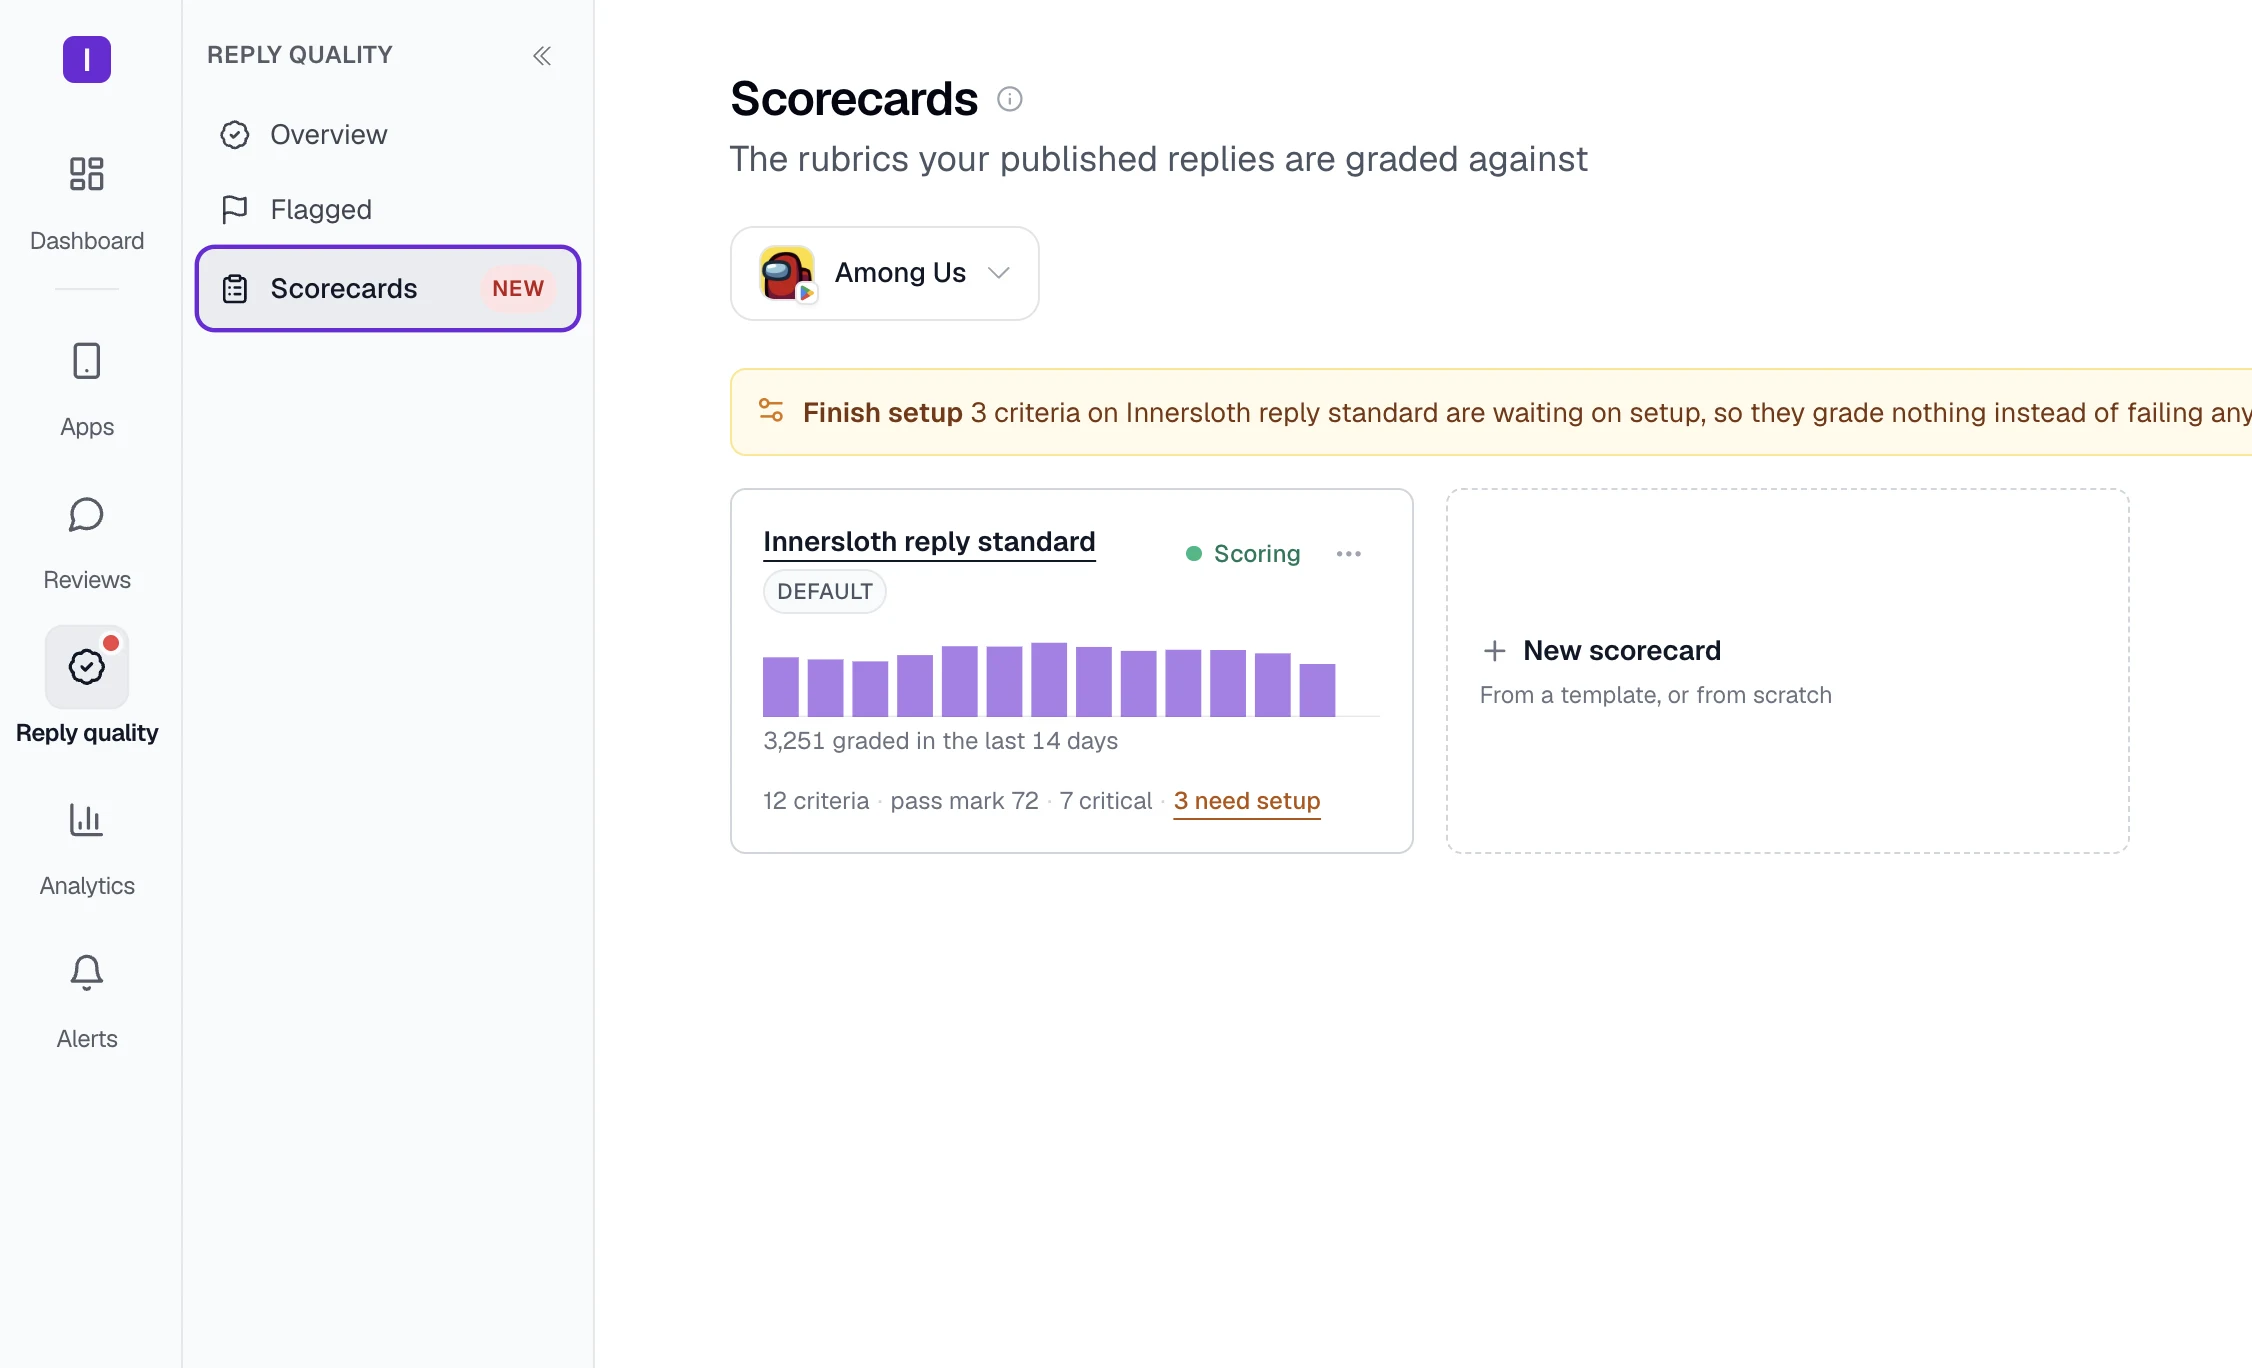
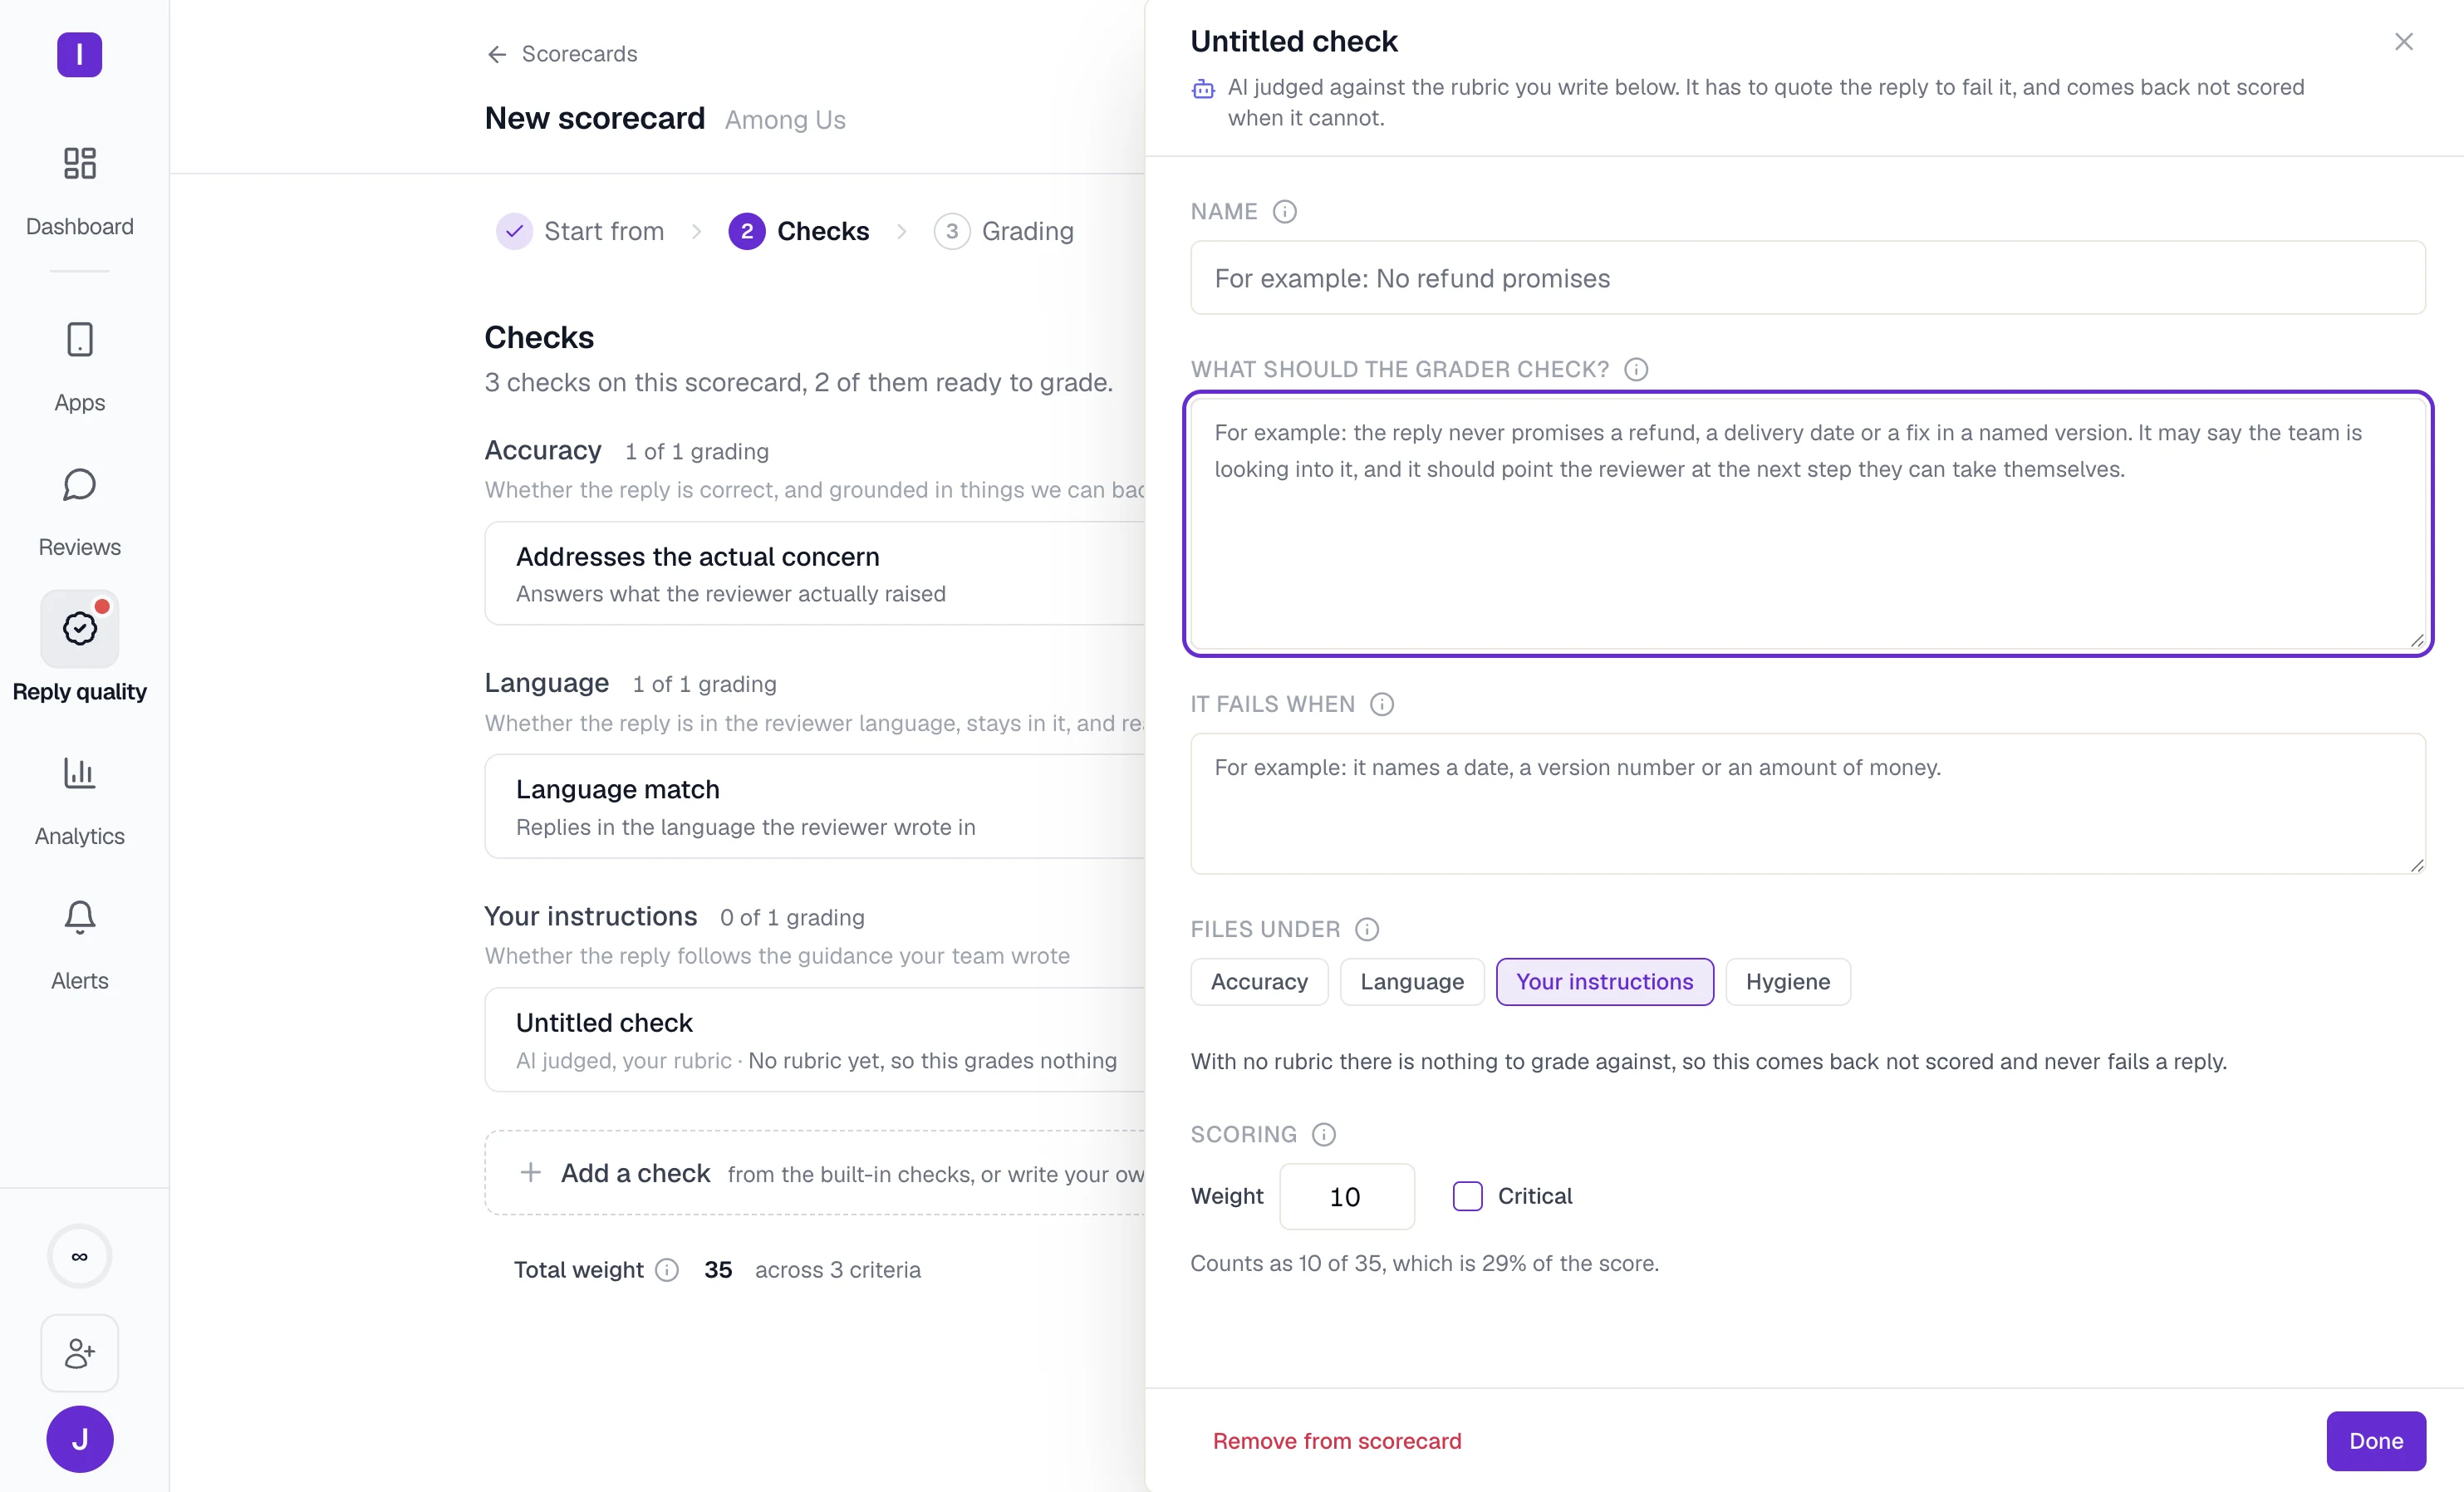
Build a checklist, called a scorecard, from your reply guidelines. Choose the checks and passing score. Mark mistakes such as invented refund policies as critical, so a polite tone cannot cancel out a wrong answer.
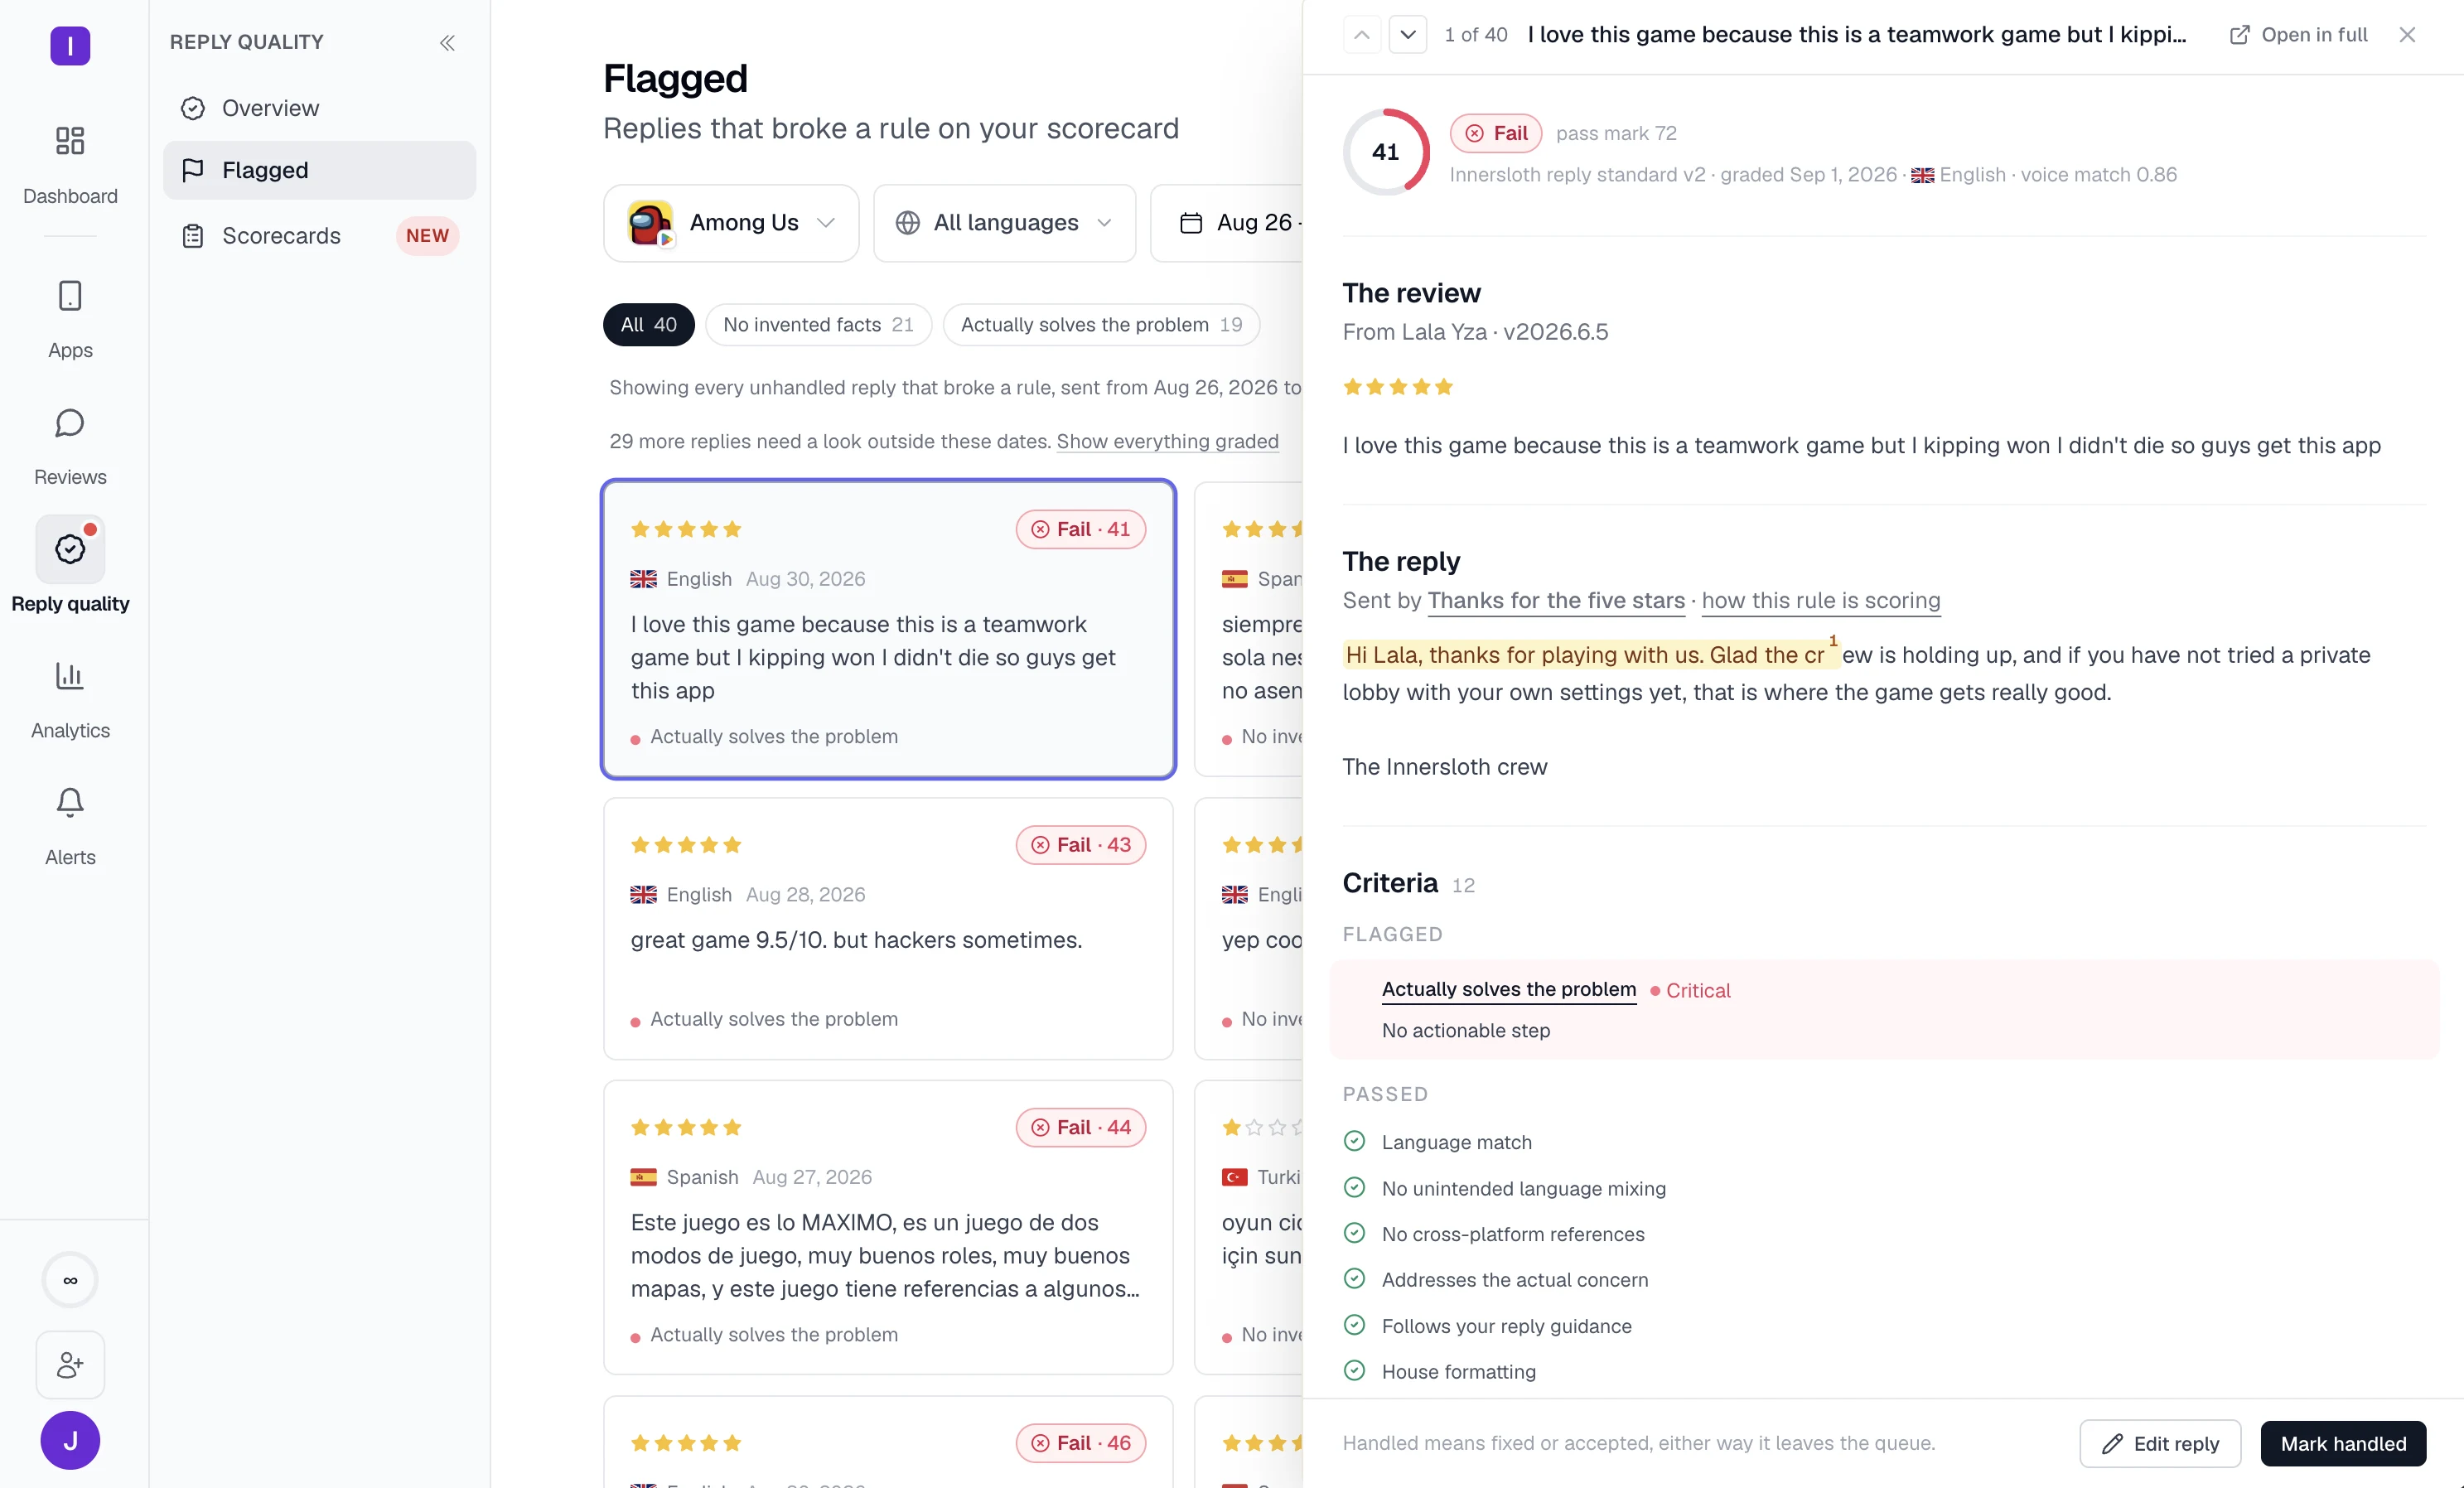
Filter flagged replies by the check they failed, language, or app. Open a result to read the original review, your published answer, and the text behind the flag, even in a language you do not read well enough to proofread the whole reply. You can judge the finding before deciding what to do.
Apply the same checklist to AI and human replies. Review the failures and see whether quality is improving across rules and languages.
Choose your checks, add custom ones, and track the share of replies that pass. Compare rules and languages to find where quality drops. Each result keeps the checklist version used to score it.


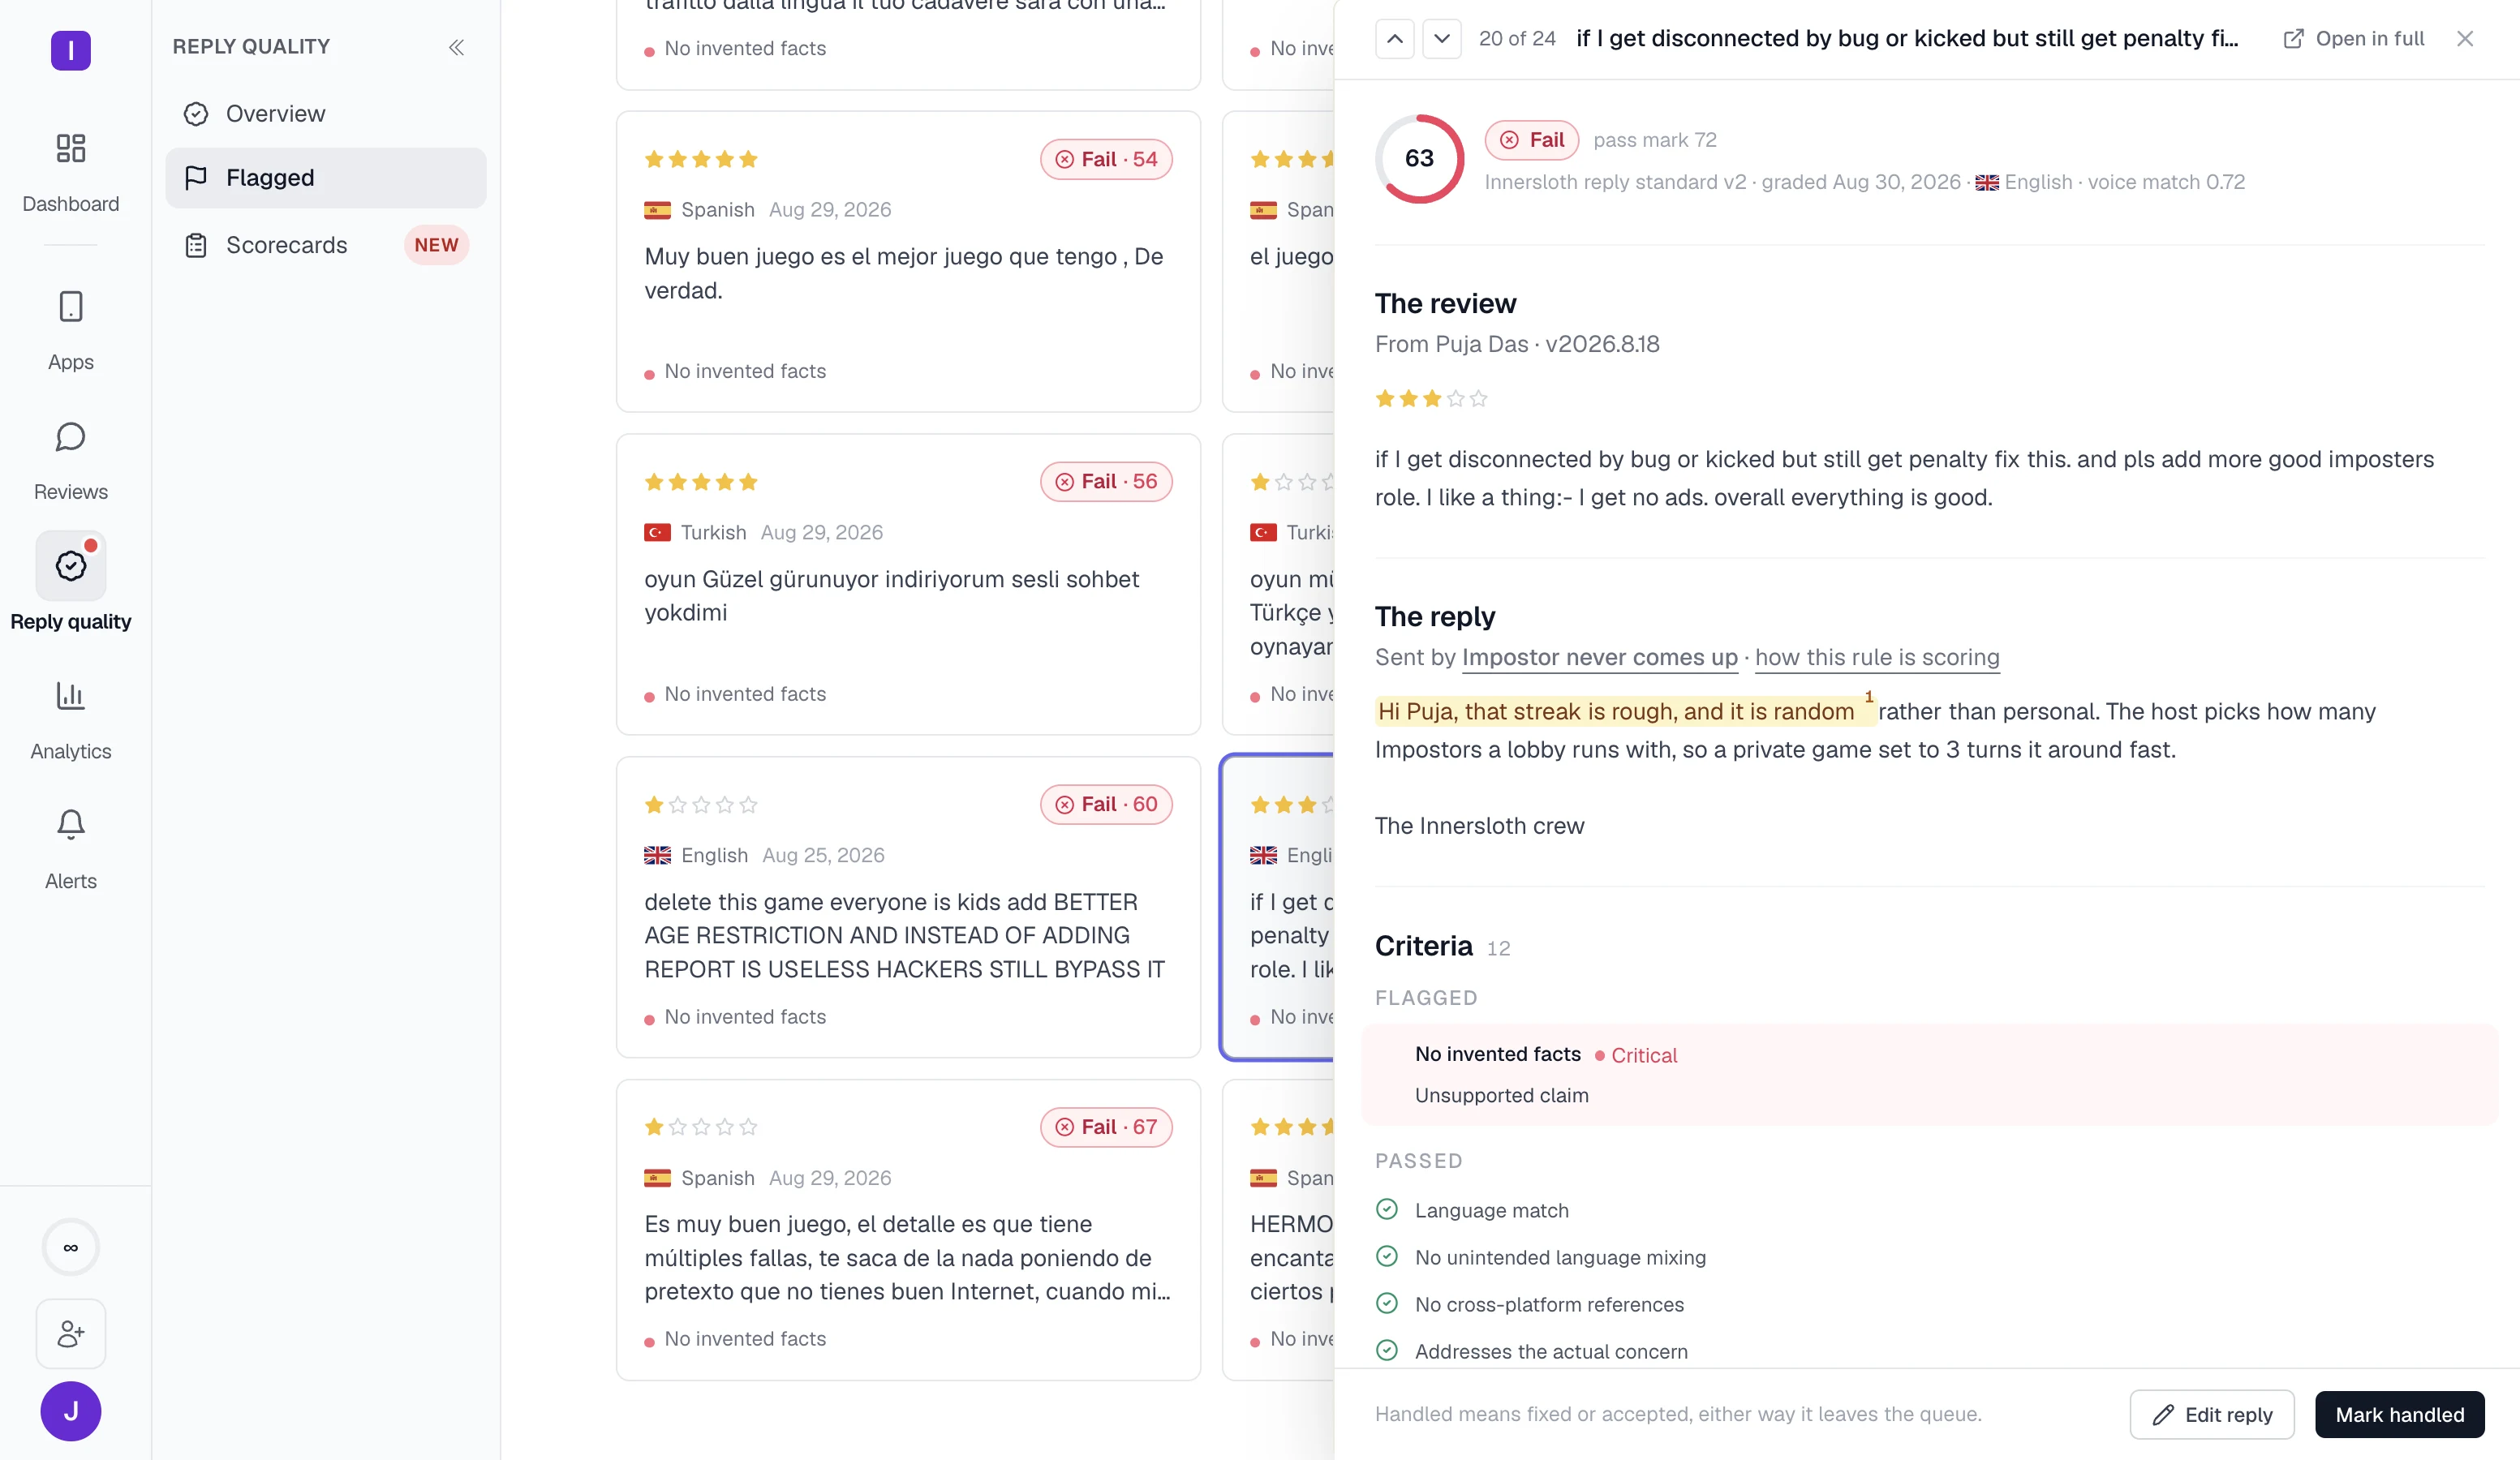
Flag answers that invent a feature, fix, or refund policy. Mark this check as critical when a promise your team cannot keep should fail the reply outright.
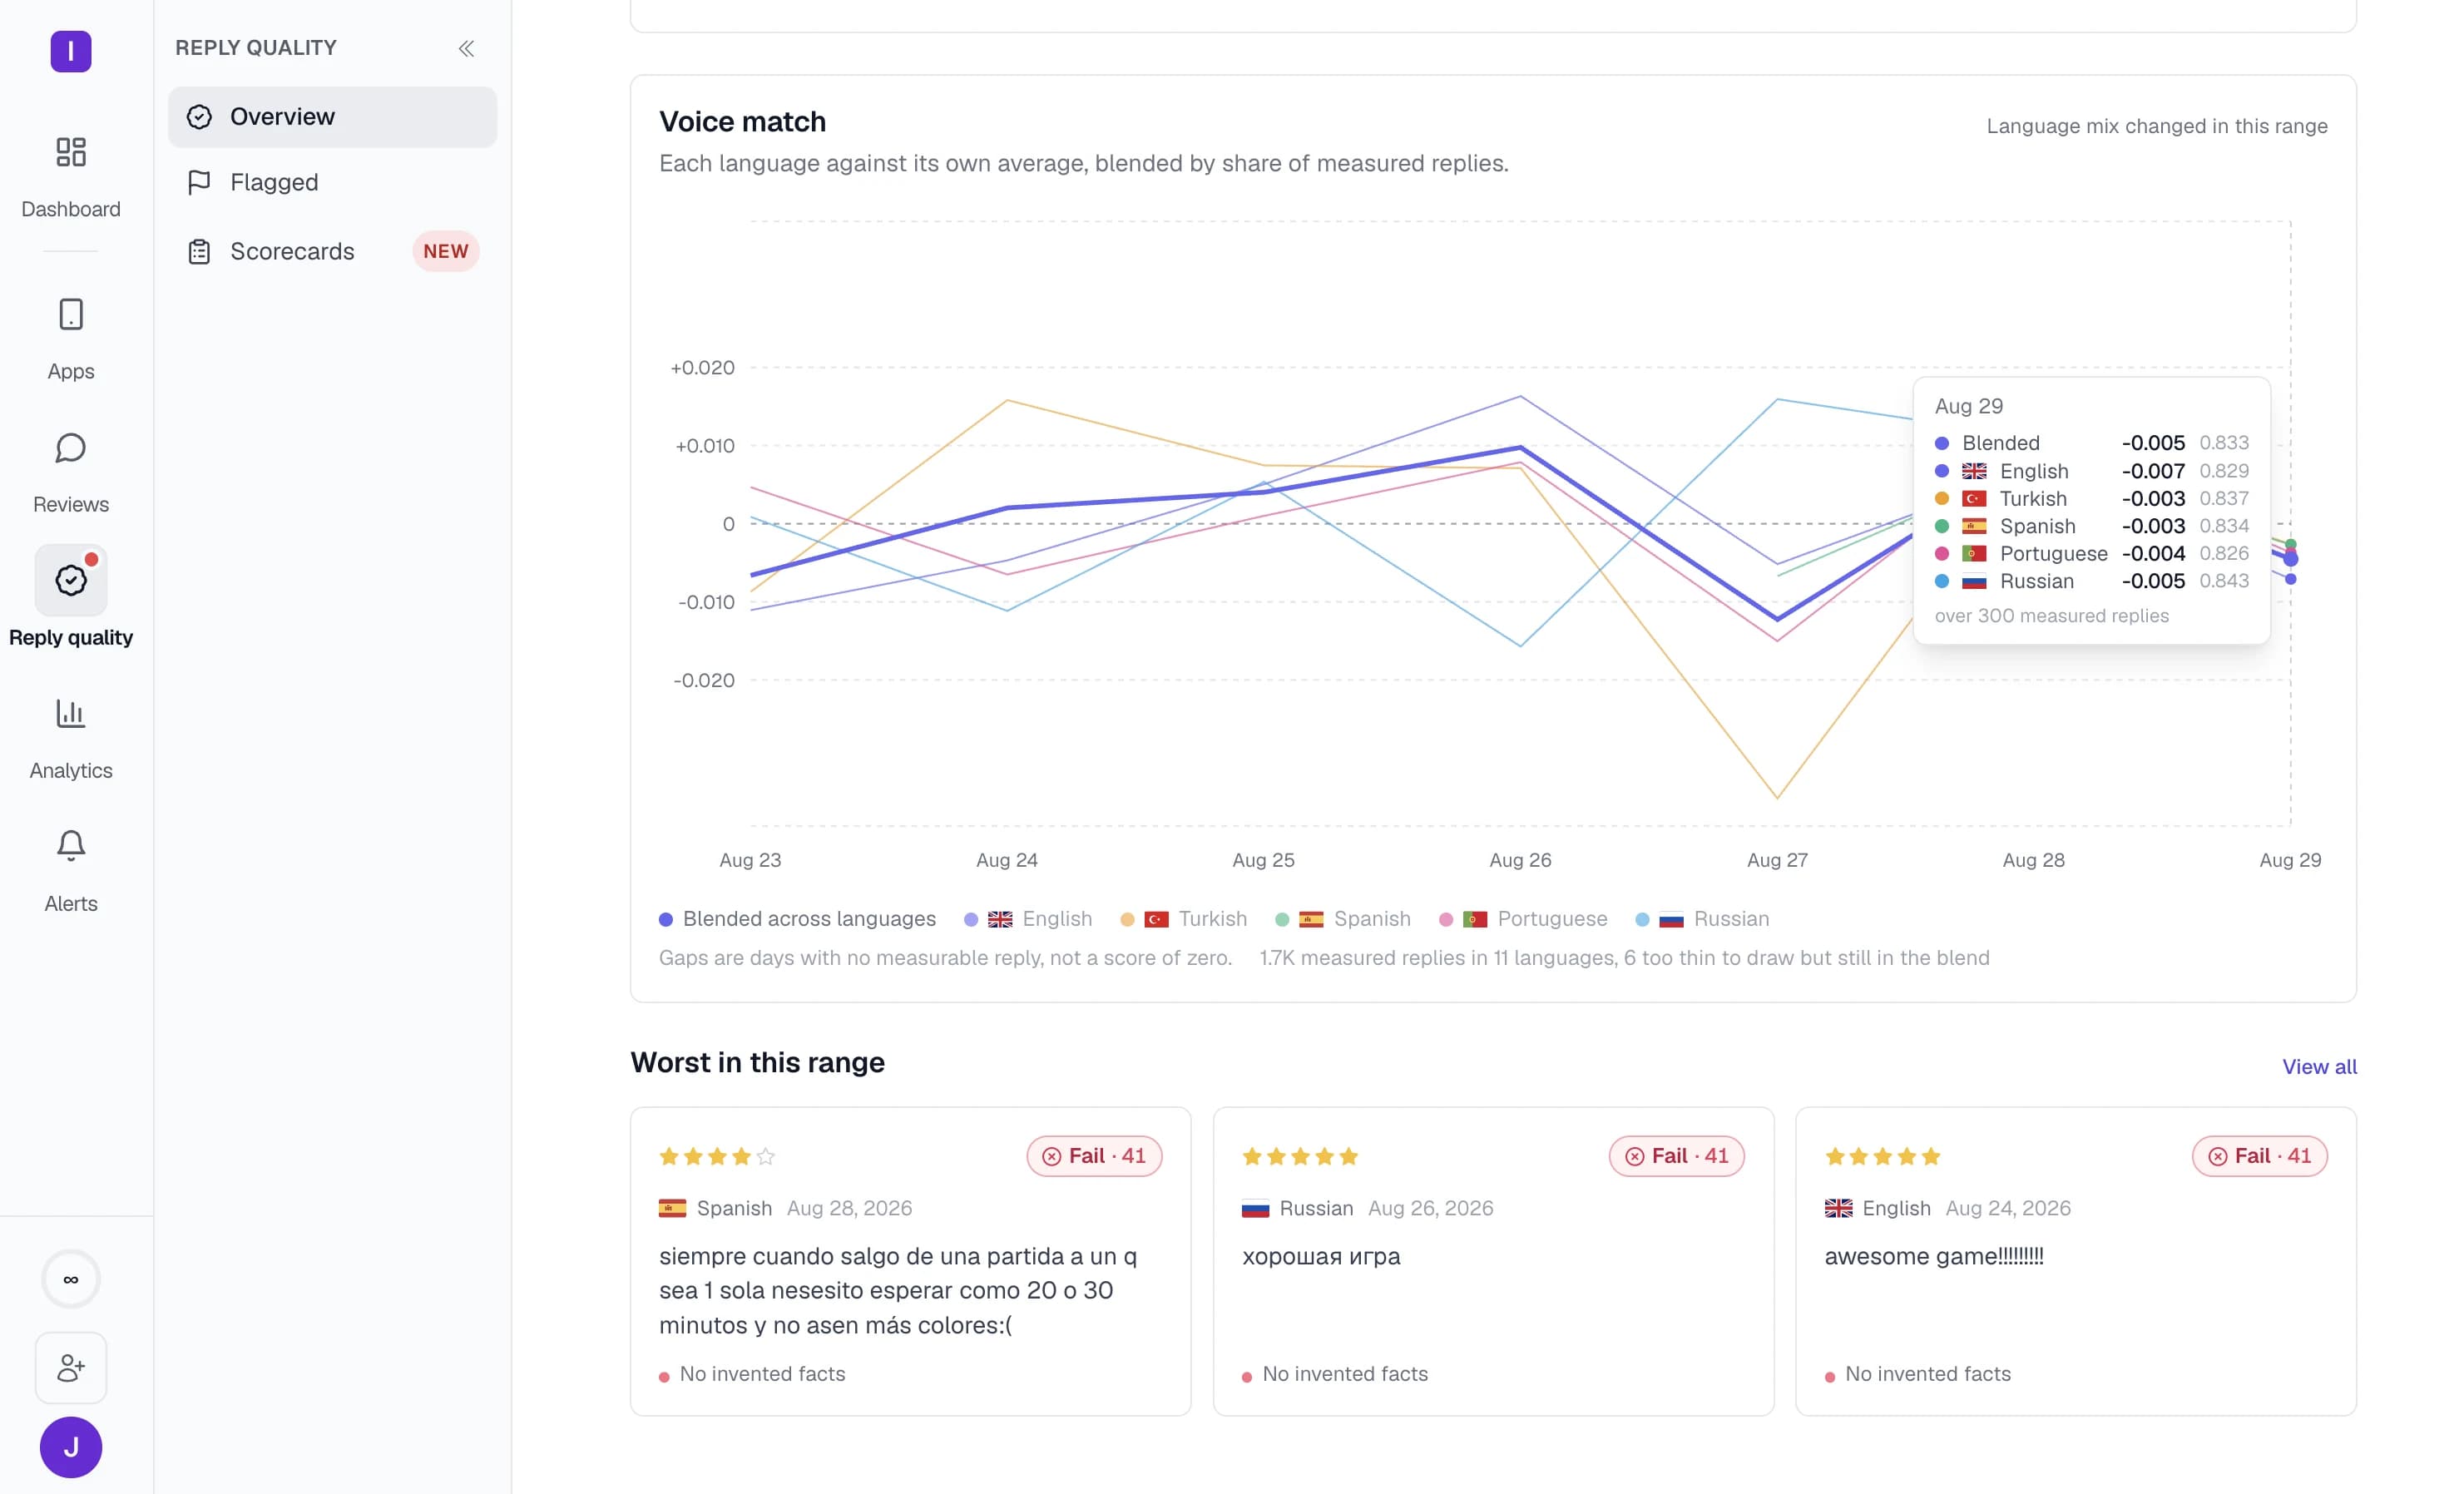
Compare replies with examples written by your own team, separately for each language. AppReply shows where there is enough history to check your voice and where there is not.
Included in Pro
Pro includes your quality checklist, ongoing checks, a flagged-reply queue, quality trends, and brand-voice checks. It also includes smart monitoring, full review analytics, and AI replies with MAX.
When AppReply manages setup, Enterprise can include a commitment that 95% of replies measured in an agreed window meet the scorecard set with your team. Reply Quality shows the exceptions.
Choose which replies to monitor and define your quality checklist. Once enabled, the monitor checks new published replies in the background and collects failures for your team.
Included in Pro · Checks AI drafts before publishing and all or selected replies after
Connect the app and select the published replies you want checked. AI and human replies can be measured against the same standard.
Choose the checks, decide which mistakes should always fail a reply, and set a passing score.
Enable the monitor to check matching replies as they publish. Filter the flagged replies by check, language, or app, and read the original review, answer, and reason together.
See whether failures cluster around a particular automation rule or language, and use that pattern to focus your review.
Past results keep the version they were scored against, so you can tell which standard applied at the time.
In a controlled test, Reply Quality caught 31 of 32 deliberately added mistakes and reported no false failures. This internal test is not a measure of accuracy across customer accounts. Methodology is available on request.
FAQ
Your replies sit under the reviews prospective users read. Watching the rating and answering fast leave one question open: was the reply accurate, in the reviewer’s language, and in your own voice? AppReply closes the loop by checking your published replies, all of them or just the ones you choose, against your scorecard. Mark a guideline critical and breaking it fails the reply outright.
A scorecard is your reply-quality checklist. It can check whether the reply answers the concern, offers a solution, uses the right language, avoids made-up facts, follows your guidance, and points to the right support channel. Choose how much each check matters, set a passing score, and mark any mistakes that should always fail a reply.
Yes. AI drafts are checked against your scorecard before they publish, and sent back for a rewrite when they fail. Published replies are graded too, whether AI or a person wrote them, and you can compare results by reply rule or language.
That check is marked “not scored” and does not count as a pass or failure. When a check does pass or fail, you can read the supporting text to see why.
No. Your checklists, reply history, and product information stay within your account and are used to provide your service. They are not used to train shared AI models.
10-day Pro trial · No credit card